Using SQL
marimo lets you mix and match Python and SQL: Use SQL to query Python dataframes (or databases like SQLite and Postgres), and get the query result back as a Python dataframe.
For a video overview on how to use SQL in marimo, watch our YouTube tutorial.
To create a SQL cell, you first need to install additional dependencies, including duckdb:
Examples
For example notebooks, check out
examples/sql/ on GitHub.
Example
In this example notebook, we have a Pandas dataframe and a SQL cell that queries it. Notice that the query result is returned as a Python dataframe and usable in subsequent cells.
Creating SQL cells
You can create SQL cells in one of three ways:
- Right-click an "add cell" button ("+" icon) next to a cell and choose "SQL cell"
- Convert a empty cell to SQL via the cell context menu
- Click the SQL button that appears at the bottom of the notebook
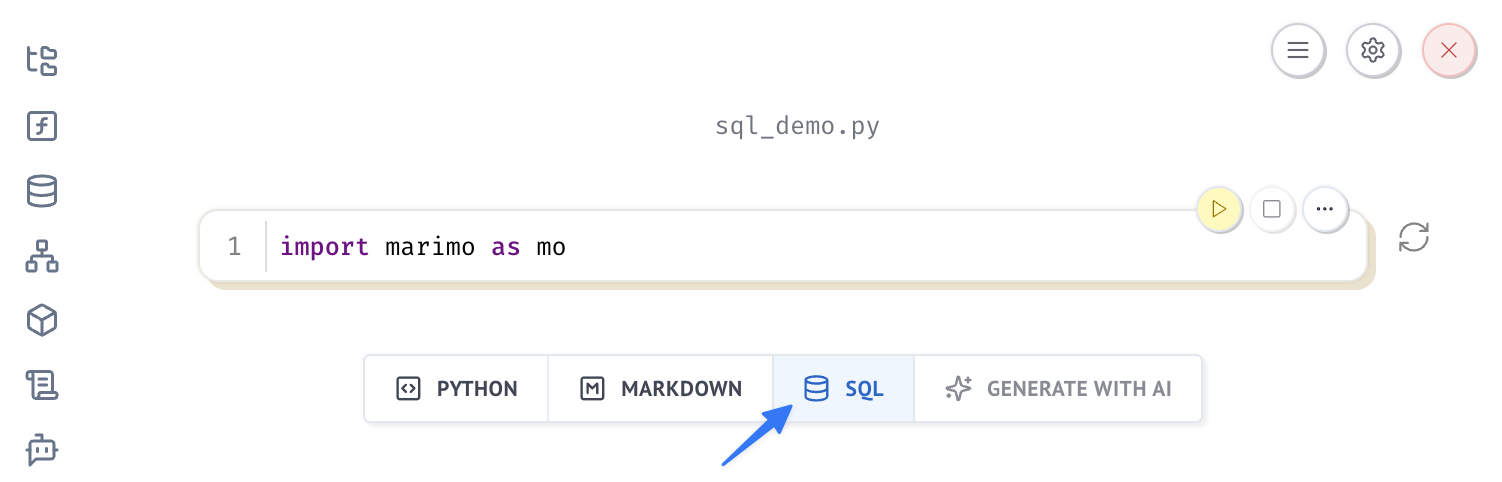
This creates a "SQL" cell for you, which is syntactic sugar for Python code. The underlying code looks like:
Notice that we have an output_df variable in the cell. This contains
the query result, and is a Polars DataFrame (if you have polars installed) or
a Pandas DataFrame (if you don't). One of them must be installed in order to
interact with the query result.
The SQL statement itself is an f-string, letting you
interpolate Python values into the query with {}. In particular, this means
your SQL queries can depend on the values of UI elements or other Python values,
and they are fit into marimo's reactive dataflow graph. The values become part
of the SQL text, so read the section on avoiding SQL injection
before interpolating input that other people can control.
SQL Output Types
marimo supports different output types for SQL queries, which is particularly useful when working with large datasets. You can configure this in your application configuration in the top right of the marimo editor.
The available options are:
native: Uses DuckDB's native lazy relation (recommended for best performance)lazy-polars: Returns a lazy Polars DataFramepandas: Returns a Pandas DataFramepolars: Returns an eager Polars DataFrameauto: Automatically chooses based on installed packages (first triespolarsthenpandas)
For best performance with large datasets, we recommend using native to avoid loading the entire result set into memory and to more easily chain SQL cells together. By default, only the first 10 rows are displayed in the UI to prevent memory issues.
Set a default
The default output type is currently auto, but we recommend explicitly setting the output type to native for best performance with large datasets or polars if you need to work with the results in Python code. You can configure this in your application settings.
Reference a local dataframe
You can reference a local dataframe in your SQL cell by using the name of the Python variable that holds the dataframe. If you have a database connection with a table of the same name, the database table will be used instead.
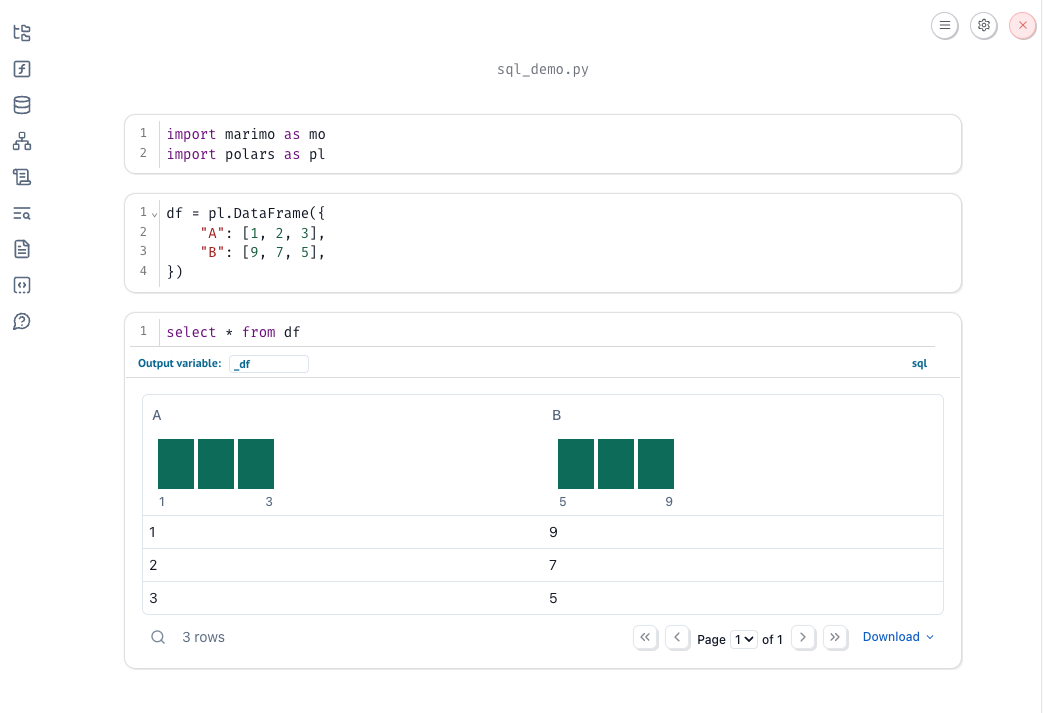
Since the output dataframe variable (_df) has an underscore, making it private, it is not referenceable from other cells.
Reference the output of a SQL cell
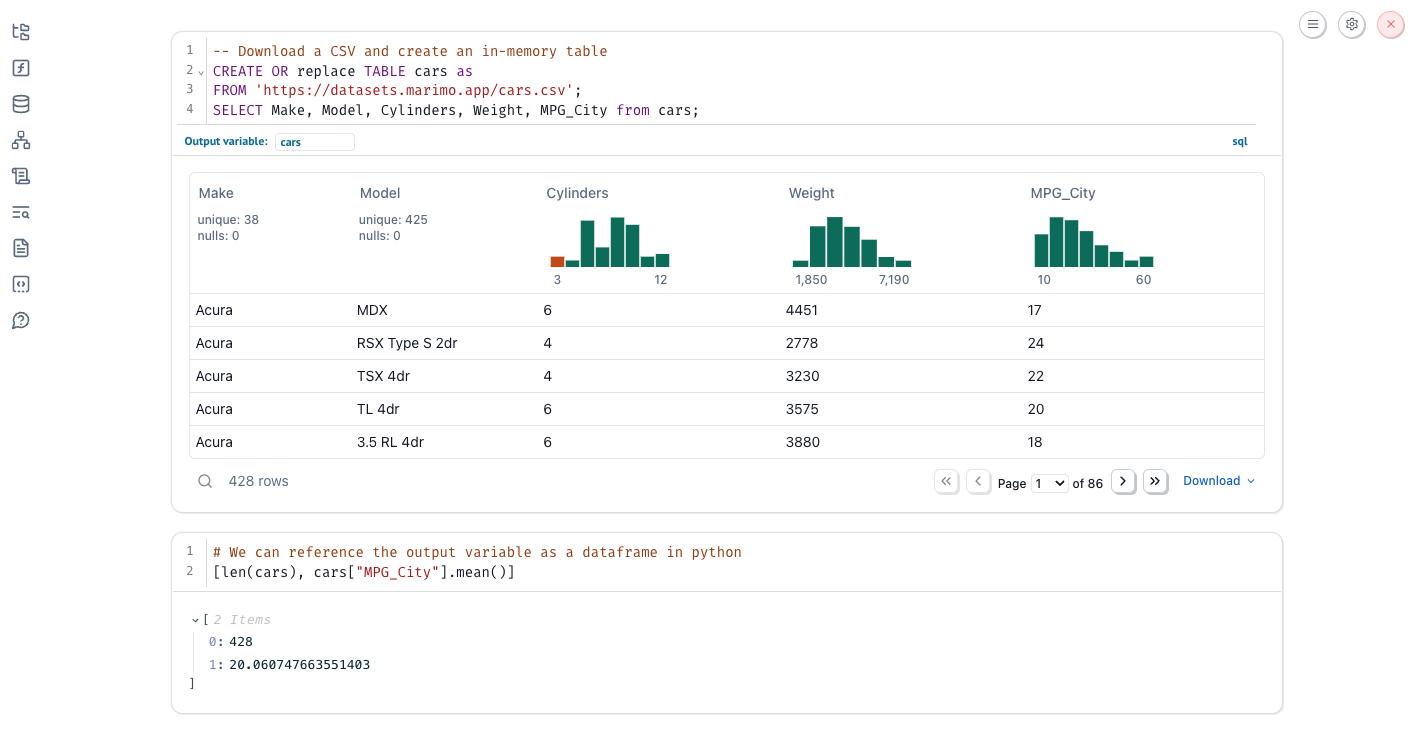
Defining a non-private (non-underscored) output variable in the SQL cell allows you to reference the resulting dataframe in other Python and SQL cells.
Querying files, databases, and APIs
In the above example, you may have noticed we queried an HTTP endpoint instead of a local dataframe. We are not only limited to querying local dataframes; we can also query files, databases such as Postgres and SQLite, and APIs:
-- or
SELECT * FROM 's3://my-bucket/file.parquet';
-- or
SELECT * FROM read_csv('path/to/example.csv');
-- or
SELECT * FROM read_parquet('path/to/example.parquet');
For a full list you can check out the duckdb extensions. You can also check out our examples on GitHub.
Refreshing SQL queries
If you'd like to refresh your SQL cells automatically, you can wire a UI element into the SQL cell's dependency graph.
Periodic refresh with mo.ui.refresh
Add a mo.ui.refresh control and reference it in your SQL query. Because SQL cells use f-strings, include the refresh control in a SQL comment so it does not affect the query:
Each time the refresh timer fires, the SQL cell re-runs. See the refresh recipe for more details.
Manual refresh with a button
For on-demand refresh, add a mo.ui.button and reference it in the cell that runs your query.
In a SQL cell, reference the button in a comment:
Other UI elements
SQL queries can interpolate any Python value, so dropdowns, sliders, text inputs, and other UI elements already trigger re-queries when their values change. See the parametrizing_sql_queries.py example on GitHub. If other people can type into a text input, bind its value as a parameter instead; see the section on avoiding SQL injection.
Escaping SQL brackets
Our "SQL" cells are really just Python under the hood to keep notebooks as pure Python scripts. By default, we use f-strings for SQL strings, which lets you interpolate Python values into SQL like SELECT * from table where value < {min}.
To escape real {/} that you don't want interpolated, use double {{...}}:
Avoiding SQL injection
Using {} inserts a Python value into the SQL text before the query runs. It is string formatting, not parameter binding, so the query can include any Python value that can be coerced into a string. This approach works well for values your own code sets.
However, if someone else can supply the value, they can change the query, so don't interpolate it directly. Examples include a mo.ui.text in a shared app, mo.query_params(), and data from files or APIs you don't control.
Unsafe: interpolating untrusted input
If species is a text input, typing setosa' OR '1'='1 makes this query
return every row. Other inputs can end the statement and run new ones, for
example to create or drop tables.
Bind values with parameters
To use an untrusted value, pass it to the database separately from the SQL
text with parameter binding. The database never parses the value as SQL.
marimo's SQL cells don't accept parameters, so you'll need to use a Python cell instead. With DuckDB, use ?
placeholders and a list:
import duckdb

result = duckdb.sql(
    "SELECT * FROM df WHERE species = ?",
    params=[species.value],
).pl()
or named $name placeholders and a dictionary:
result = duckdb.sql(
    "SELECT * FROM df WHERE species = $species",
    params={"species": species.value},
).pl()
Typing setosa' OR '1'='1 now matches no rows, because it is compared with
species as an ordinary string. See DuckDB's
prepared statements
documentation for more. For other databases, use the parameter binding of your
database's Python library; placeholder syntax varies between libraries.
Keep the query as the only positional argument
marimo reads the query to find the dataframes and tables it uses, like df
above, so the cell reruns when they change. For duckdb.sql and
duckdb.execute, it does this only when the query is a string literal and
the only positional argument. Write the query inline and pass parameters by
keyword: params= for duckdb.sql, parameters= for duckdb.execute.
Use an allowlist for table and column names
Parameters can't stand in for identifiers such as table or column names. To let users of a marimo app choose an identifier safely, offer them a fixed set of choices, for example with a mo.ui.dropdown:
sort_column = mo.ui.dropdown(
    options=["species", "petal_length"],
    value="species",
    label="Sort by",
)
sort_column
and interpolate its value in a SQL cell:
Connecting to a custom database
There are two ways to connect to a database in marimo:
Using the UI
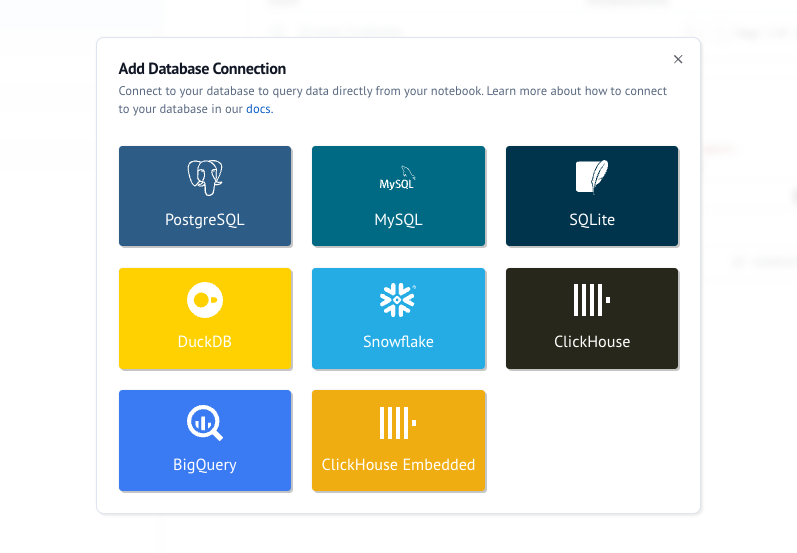
Click the "Add Database Connection" button in your notebook to connect to PostgreSQL, MySQL, SQLite, DuckDB, Snowflake, or BigQuery databases. The UI will guide you through entering your connection details securely. Environment variables picked up from your dotenv can be used to fill out the database configuration fields.
Detecting data sources from your environment
marimo scans your kernel's environment for connection details it recognizes and offers them as Quick add suggestions. Click a suggestion to insert a ready-to-run cell.

| Integration | Detected from |
|---|---|
| PostgreSQL | PGHOST, PGUSER, PGDATABASE (plus PGPORT, PGPASSWORD) |
| MySQL | MYSQL_HOST, MYSQL_USER, MYSQL_DATABASE, and MYSQL_PASSWORD/MYSQL_PWD (plus MYSQL_TCP_PORT) |
| Trino | TRINO_HOST, TRINO_USER, TRINO_CATALOG (plus TRINO_PORT, TRINO_PASSWORD, TRINO_SCHEMA) |
| Databricks SQL warehouse | DATABRICKS_SQL_WAREHOUSE_ID (plus DATABRICKS_CONFIG_PROFILE) |
| DuckDB | DUCKDB_PATH or a local DUCKDB_DATABASE (plus DUCKDB_READ_ONLY) |
| MotherDuck | MOTHERDUCK_DATABASE, an md: URL in DUCKDB_DATABASE, or MOTHERDUCK_TOKEN / DUCKDB_MOTHERDUCK_TOKEN / motherduck_token |
| Quack | A quack: URI in QUACK_DATABASE or DUCKDB_DATABASE (plus QUACK_TOKEN / QUACK_API_KEY) |
| PySpark (Spark Connect) | SPARK_REMOTE |
| PyIceberg catalogs | PYICEBERG_CATALOG__<name>__* environment variables, or catalogs resolved from a .pyiceberg.yaml file |
Only the names of environment variables are shown in the UI — their values are never sent to the frontend.
If you'd like to connect to a database that isn't supported by the UI, you can use the code method below, or submit a feature request.
Using code
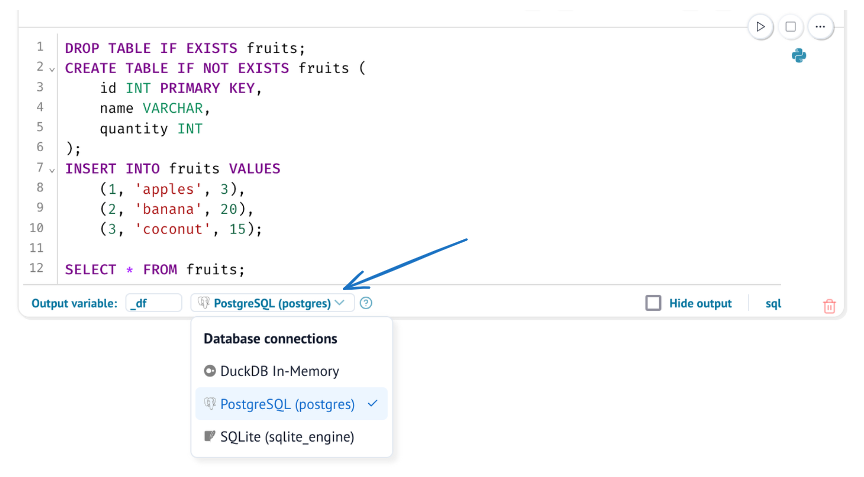
You can bring your own database via a connection engine with one of the following libraries
By default, marimo uses the in-memory duckdb connection.
List of supported databases
Updated: 2025-04-30. This list is not exhaustive.
| Database | Library |
|---|---|
| Amazon Athena | sqlalchemy, sqlmodel, ibis |
| Amazon Redshift | sqlalchemy, sqlmodel |
| Apache Drill | sqlalchemy, sqlmodel |
| Apache Druid | sqlalchemy, sqlmodel, ibis |
| Apache Hive and Presto | sqlalchemy, sqlmodel |
| Apache Solr | sqlalchemy, sqlmodel |
| BigQuery | sqlalchemy, sqlmodel, ibis |
| ClickHouse | clickhouse_connect, chdb |
| CockroachDB | sqlalchemy, sqlmodel |
| Databricks | sqlalchemy, sqlmodel, ibis |
| dlt | ibis |
| Datafusion | ibis |
| DuckDB | duckdb |
| EXASolution | sqlalchemy, sqlmodel, ibis |
| Elasticsearch (readonly) | sqlalchemy, sqlmodel |
| Firebolt | sqlalchemy, sqlmodel |
| Flink | ibis |
| Google Sheets | sqlalchemy, sqlmodel |
| Impala | sqlalchemy, sqlmodel, ibis |
| Microsoft Access | sqlalchemy, sqlmodel |
| Microsoft SQL Server | sqlalchemy, sqlmodel, ibis |
| MonetDB | sqlalchemy, sqlmodel |
| MySQL | sqlalchemy, sqlmodel, ibis |
| OpenGauss | sqlalchemy, sqlmodel |
| Oracle | sqlalchemy, sqlmodel, ibis |
| PostgreSQL | sqlalchemy, sqlmodel, ibis |
| PySpark | ibis |
| RisingWave | ibis |
| SAP HANA | sqlalchemy, sqlmodel |
| Snowflake | sqlalchemy, sqlmodel, ibis |
| SQLite | sqlalchemy, sqlmodel, ibis |
| Teradata Vantage | sqlalchemy, sqlmodel |
| TimePlus | sqlalchemy, sqlmodel |
| Trino | sqlalchemy, sqlmodel, ibis |
Define the engine as a Python variable in a cell:
ClickHouse Connect enables remote connections to ClickHouse databases. Refer to the official docs for more configuration options.
Warning
chDB is still new. You may experience issues with your queries. We recommend only using one connection at a time. Refer to chDB docs for more information.
import chdb
connection = chdb.connect(":memory:")
# Supported formats with examples:
":memory:" # In-memory database
"test.db" # Relative path
"file:test.db" # Explicit file protocol
"/path/to/test.db" # Absolute path
"file:/path/to/test.db" # Absolute path with protocol
"file:test.db?param1=value1¶m2=value2" # With query parameters
"file::memory:?verbose&log-level=test" # In-memory with parameters
"///path/to/test.db?param1=value1" # Triple slash absolute path
marimo will auto-discover the engine and let you select it in the SQL cell's connection dropdown.
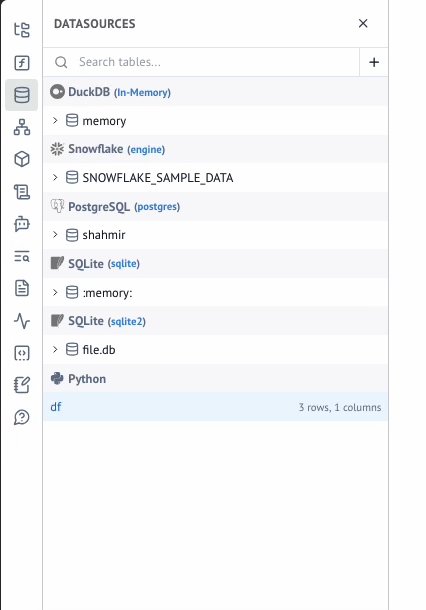
Database, schema, and table auto-discovery
marimo will automatically discover the database connection and display the database, schemas, tables, and columns in the Data Sources panel. This panels lets you quickly navigate your database schema and reference tables and columns to pull in your SQL queries.
Note
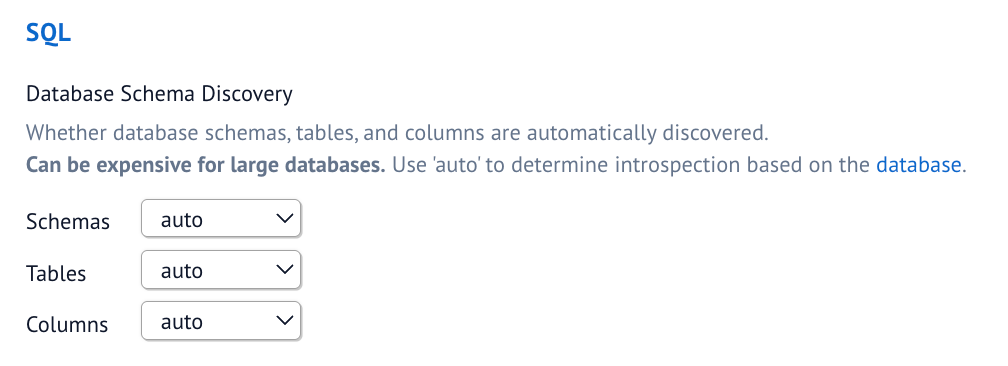
By default, marimo auto-discovers databases but may not discover tables, columns and schemas (to avoid performance issues with large databases). You can configure this behavior in your pyproject.toml file. Options are true, false, or "auto". "auto" will determine whether to discover based on the type of database: databases that are cheap to introspect (e.g. SQLite, Postgres, MySQL) are discovered, while data warehouses (e.g. Snowflake, BigQuery) are not:
[tool.marimo.datasources]
auto_discover_schemas = "auto"  # Default: "auto"
auto_discover_tables = "auto"   # Default: "auto"
auto_discover_columns = false   # Default: false
SQL cell autocompletion relies on discovery so it may not work if the schema has not been discovered. You can either use the Data Sources panel and expand the schemas and tables you want which will register the autocompletion semantics, or change the config set above.
You can also change these settings through the notebook settings menu (gear icon), under Packages & Data:
Catalogs
marimo supports connecting to Iceberg catalogs. You can click the "+" button in the Datasources panel or manually create a PyIceberg Catalog connection. PyIceberg supports a variety of catalog implementations including REST, SQL, Glue, DynamoDB, and more.
from pyiceberg.catalog.rest import RestCatalog

catalog = RestCatalog(
    name="catalog",
    warehouse="1234567890",
    uri="https://my-catalog.com",
    token="my-token",
)
Catalogs will appear in the Datasources panel, but they cannot be used as an engine in SQL cells. However, you can still load the table and use it in subsequent Python or SQL cells.
Utilities
marimo provides a few utilities when working with SQL
SQL Linter
Lint your SQL code and provide better autocompletions and error highlighting.
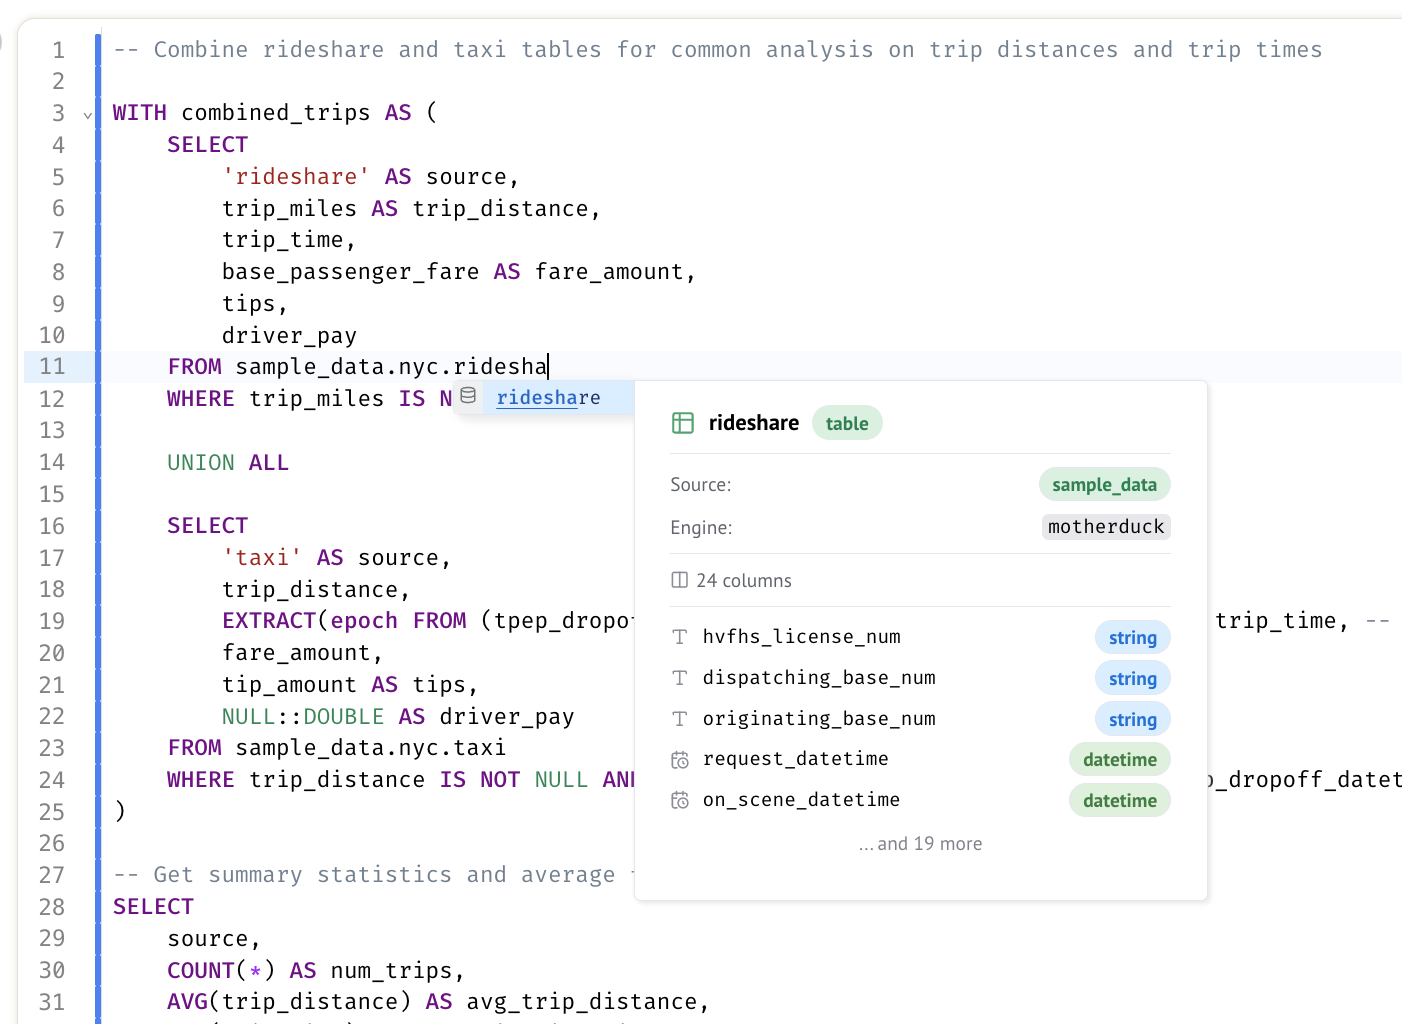
To disable the linter, you can set the sql_linter configuration to false in your pyproject.toml file or disable it in the marimo editor's settings menu.
SQL Formatting
Click on the paint roller icon at the bottom right of the SQL cell to format your SQL code.
SQL Mode
For In-Memory DuckDB, marimo offers a Validate mode that will validate your SQL as you write it.
Under the hood, this runs a debounced query in EXPLAIN mode and returns the parsed errors.
Interactive tutorial
For an interactive tutorial, run
at your command-line.
Examples
Check out our examples on GitHub.